Scan2OCR
A background text recognition option for Scan2Net scanners: books, case files, and other documents are saved directly as searchable multipage PDFs.
Developer: Image Access GmbH, Germany
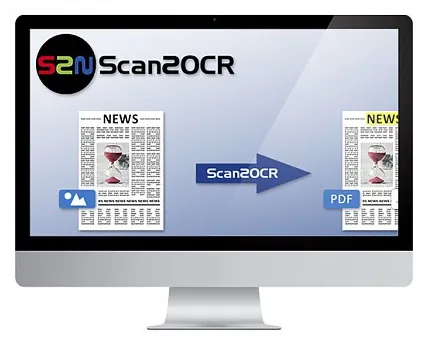
Scan2OCR is a software option that turns books, case files, and other documents into searchable multipage PDF files. Recognition is performed in the background on the scanner itself, so the operator can keep scanning without waiting for the OCR results; to avoid slowing down scanning, recognition runs at low priority.
The option uses the Tesseract OCR engine and the Leptonica page layout analysis software and supports more than 100 languages, including many Asian ones. English and German are installed on the scanner by default; the other language packs can be downloaded free of charge from the Image Access portal. No more than two recognition languages can be selected per template; the manufacturer recommends a resolution of at least 300 dpi. Scan2OCR works in ScanWizard’s Job Mode with PDF output, as well as with Batch Scan Wizard.
Features
- Searchable multipage PDFs
- Background recognition during scanning — no waiting for OCR results
- OCR runs on the scanner itself at low priority so as not to slow down scanning
- Tesseract OCR engine and Leptonica page layout analysis
- More than 100 languages, including many Asian ones; English and German preinstalled
- Additional language packs available free of charge from the Image Access portal
- Up to two recognition languages per template; recommended resolution: at least 300 dpi
Documentation
Manufacturer documents (PDF) open on the manufacturer’s website.
Manuals and specifications
Sources: imageaccess.de/…/s2n-software-options · cdn.imageaccess.de/…/FAQ-OCR.pdf · cdn.imageaccess.de/…/Product_Catalog_EN.pdf · cdn.imageaccess.de/…/WideTEK_Flatbed_PL_E_Internet.pdf · cdn.imageaccess.de/…/Prospekt_WT24F-600_EN.pdf